CS 471/671 (How to grow language models) - #10 - Fall 2026
Keywords
Summary
150 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides substantial value by offering a comprehensive overview of tokenization algorithms, their practical nuances, and a historical perspective on neural language modeling. The argumentation is well-supported with concrete examples, comparisons, and references to contemporary research, such as Super BPE and visual text representation. The instructor clearly explains both the ‘why’ and ‘how’ of each design choice, strengthening the credibility of the presented material.
Scientific Rigor, Source Quality, Title Accuracy
The lecture demonstrates high scientific rigor, with careful explanations grounded in established literature and recent developments. The sources mentioned include direct references to the Bengio 2003 paper and the Super BPE paper, though the instructor does not provide explicit URLs. The course website linked in the description provides additional resources and context. The title accurately reflects the content, which is centered on language model growth and building, and the lecture consistently aligns with this theme without deviating.
157 words
Title / Content Match
The title appropriately reflects the lecture's focus on building and scaling language models, including tokenization and a first neural language model.
Quality & Reliability
9/10
The lecture is given by an expert in the field at a top university, covers recent advances and historical context, and is technically accurate. The content is well-structured and authoritative.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Recap of BPE and introduction to WordPiece and Unigram algorithms.
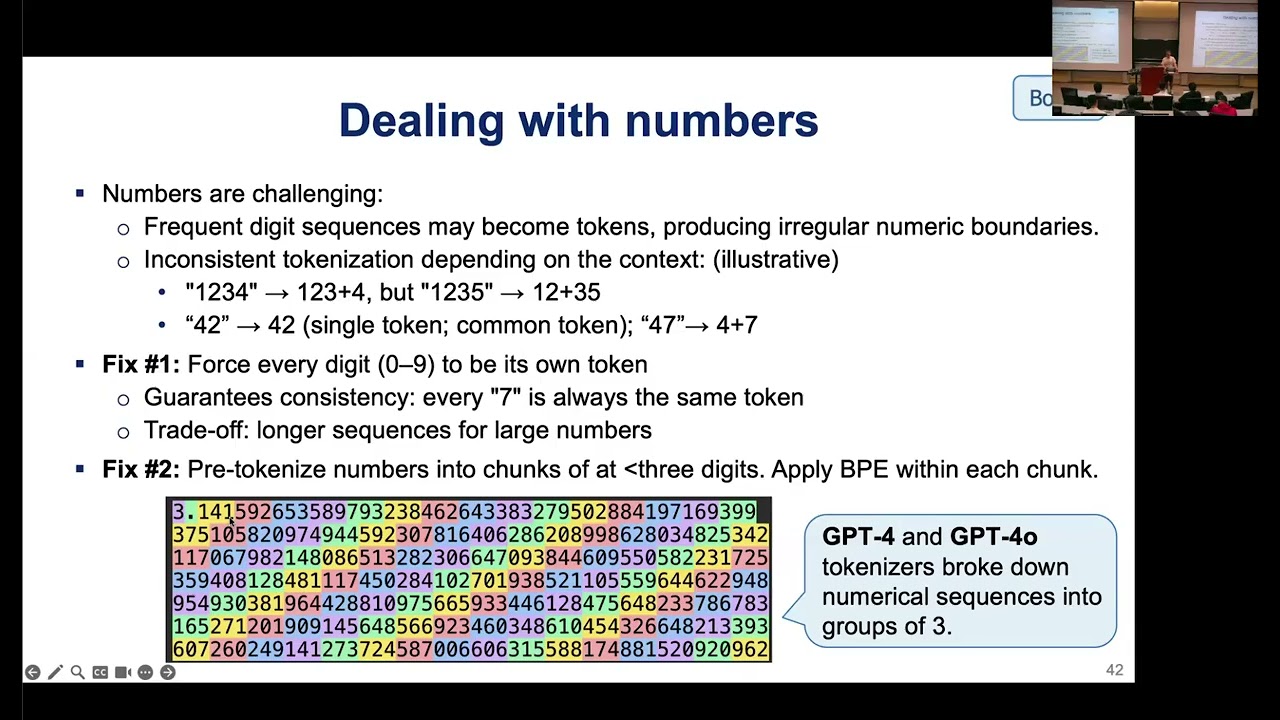
- Discussion on handling spaces and numbers in tokenization, including multi-space chunks and digit grouping.
- Analysis of vocabulary sizes, typical ranges, and the use of powers of two for tensor splitting.
- Introduction of Super BPE and representing text as visual data, citing recent developments.
- Transition to building a language model: mapping tokens to embeddings and using nn.Embedding.
- Presentation of a feed-forward language model and Yoshua Bengio's 2003 paper, including perplexity comparisons.
Cited Sources
- Course website — The official course page for CS 471/671, containing syllabus, materials, and additional resources.
Contribution & Novelties
This lecture offers a unique synthesis of tokenization best practices, combining historical context with recent advances like Super BPE and visual text representation. It bridges the gap between theoretical concepts and practical implementation, particularly in the detailed walkthrough of building a first language model with PyTorch. The emphasis on understanding trade-offs and design choices equips learners with transferable knowledge.
Pour aller plus loin :
- Byte pair encoding — Foundational algorithm for subword tokenization, directly relevant to BPE.
- SentencePiece — Library implementing Unigram and other tokenization methods, mentioned in the lecture.
- Subword tokenization — Overview of different approaches, including WordPiece and Unigram.
- A Neural Probabilistic Language Model — The seminal 2003 paper by Bengio et al., referenced in the lecture as the first feed-forward neural language model.
126 words
Radar Profile
The radar profile indicates a lecture with strong reliability and technical depth, balanced by a high quantity of information. The high quality and global scores reflect the authoritative presentation and effective teaching style.