Lecture 22 Problem +XOR
Keywords
Summary
268 words
Critical Evaluation
Value of the Information & Strength of the Argument
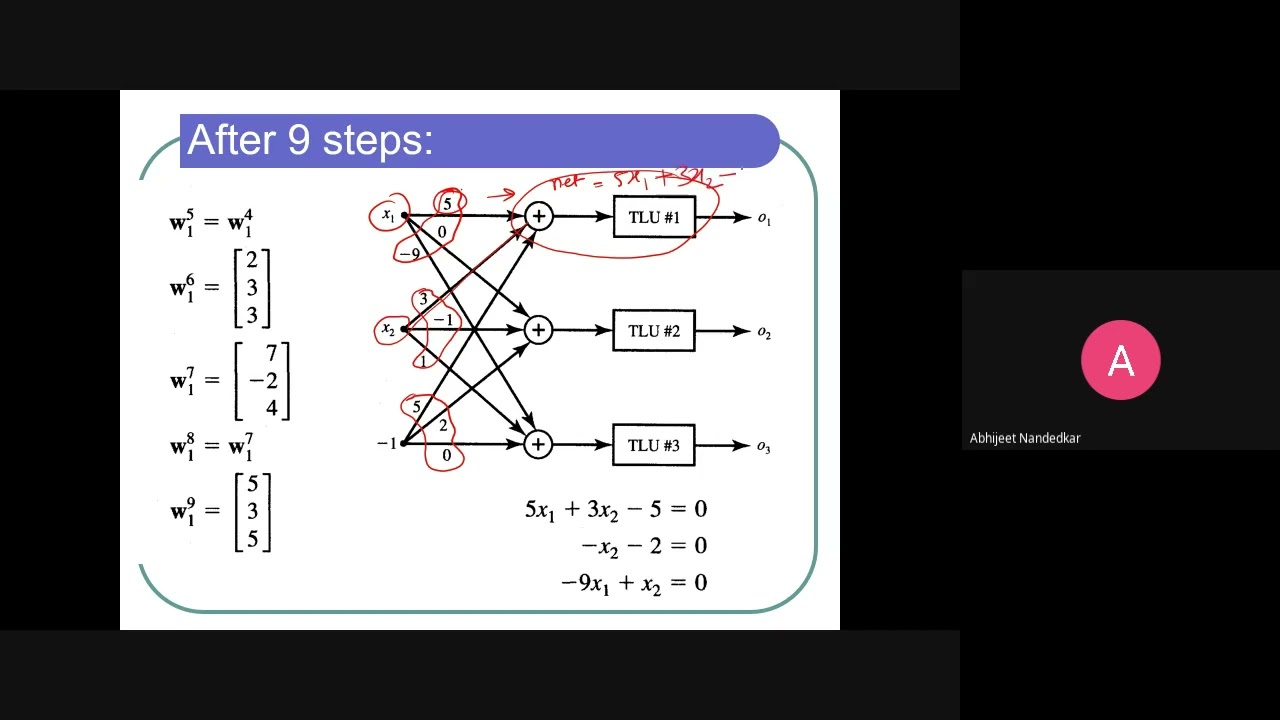
The informational value lies in the step-by-step, hand-computable demonstration of how a single-layer perceptron partitions feature space and why that partitioning fails for XOR. The instructor does not merely state that XOR is non-linearly separable; he constructs the argument by drawing the four input points, attempting several candidate lines, and showing that each attempt misclassifies at least one point. This is a genuinely pedagogical argument rather than an assertion. The derivation of decision boundaries from net = 0, and the reading of the coefficient vector as the direction of the positive half-space, is a compact and correct geometric interpretation that gives the viewer a reusable tool. The three-class example is also valuable because it shows the update rule operating selectively: only the misclassifying neuron is trained at each step, which clarifies the mechanics of the perceptron rule in a multi-output setting. The argument for multi-layer networks is built incrementally from OR and AND to XOR, which is the standard and logically sound route. The main weakness is that the argument is delivered orally and relies on board drawings that the transcript cannot fully convey; some numerical statements are ambiguous (for example the third neuron’s line is read as ‘minus 9 x1 plus x2’ in one place and ‘minus x1 plus x2’ in another), which could confuse a viewer trying to reproduce the arithmetic. The transition to backpropagation is announced rather than developed, so the lecture’s argumentative payoff on that topic is deferred to a later session.
Scientific Rigor, Source Quality, Title Accuracy
No sources, papers, textbooks or datasets are cited at any point, and the video description is empty, so there is no external reference apparatus to evaluate. The scientific content itself is standard textbook material on the perceptron, the delta rule and linear separability, and it is presented accurately: the OR and AND thresholds are correct, the XOR non-separability claim is correct, and the two-line-plus-combiner construction is a valid minimal solution. The rigour is therefore that of a competent classroom exposition rather than of a sourced review. The title ‘Problem +XOR’ is adequate and honest: the lecture does address a worked problem and then introduces XOR, though a viewer might expect the XOR treatment to be complete when in fact it is only set up and postponed to the next class. No comments were provided for analysis.
397 words
Title / Content Match
The title 'Problem +XOR' matches the content well: the lecture works through a three-class multi-neuron training problem and then introduces the XOR problem as the canonical non-linearly-separable case. The title is terse but not misleading.
Quality & Reliability
7/10
The lecture is delivered by an instructor in a structured academic course setting and the technical content is internally consistent: the perceptron learning rule, the decision-boundary derivation, the OR/AND/XOR analysis and the multi-neuron XOR construction are all standard, correct and reproducible by hand. No external sources, papers or datasets are cited, and the description contains no links, so the material cannot be cross-checked against published references. The treatment is mathematically sound but informal (spoken lecture, board work, occasional slips such as 'minus 9 x1' where the coefficient is read inconsistently), which limits the score to a solid but not exemplary level.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Recap of multi-category networks: one output neuron per class and the desired response vector of length equal to the number of classes.
- Presentation of the three-class training problem with inputs X1, X2, X3 and the distinction between training-set and test-set performance reporting.
- First training sample applied: only the neuron producing the wrong answer is updated by the perceptron learning rule.
- After about nine iterations the weights settle; derivation of each neuron's decision boundary by setting the net input to zero.
- Geometric reading of the coefficient vector as the direction of the positive firing half-space for each of the three neurons.
- Combination of the three half-spaces to identify the class-1, class-2 and class-3 regions and the shaded indecision zone.
- Transition to the delta learning rule with continuous activation functions (tanh or logistic) and the introduction of the derivative term in the update.
- Announcement of the core topic: multi-layer feedforward networks trained by backpropagation, the generalized delta rule used in deep learning.
- OR gate implemented by a single neuron with weights 1,1 and threshold 0.5; AND gate with the same weights and threshold 1.5.
- XOR presented as the canonical non-linearly-separable problem; demonstration that no single line can separate the four input points.
- Two-neuron construction implementing two lines whose overlapping positive half-spaces isolate class 1, plus a third neuron to combine the outputs.
Contribution & Novelties
This is a course lecture rather than a research contribution, so its originality lies in exposition rather than in new results. Its value is the explicit, hand-worked bridge from the single-layer perceptron to the necessity of multi-layer architectures: the viewer sees the three-class update rule in operation, sees the decision boundaries derived algebraically and interpreted geometrically, and then sees the same geometric reasoning fail on XOR. The two-line-plus-combiner construction is presented as a concrete, minimal solution rather than as an abstract claim, which makes the motivation for hidden layers tangible. The lecture also flags the practical convention of reporting test-set rather than training-set performance, a small but useful methodological remark.
Pour aller plus loin :
- Perceptron — Background on the single-layer model and the learning rule used throughout the first half of the lecture.
- XOR problem and linear separability — Formal treatment of why XOR cannot be solved by a single linear classifier.
- Backpropagation — The generalized delta rule announced at the end of the lecture as the core of multi-layer training.
- Marvin Minsky and Seymour Papert, ‘Perceptrons’ (1969) — The classical analysis of the limitations of single-layer perceptrons, including the XOR case.
- Multilayer perceptron — Architecture context for the hidden-layer construction sketched in the final minutes.
207 words
Radar Profile
The profile is that of a solid classroom exposition: high on information quality and technical level, moderate on quantity because the treatment is selective and partly deferred to the next session, and moderate on global reliability because no external references are provided. The imbalance between quality and reliability reflects accurate standard material presented without a sourcing apparatus.